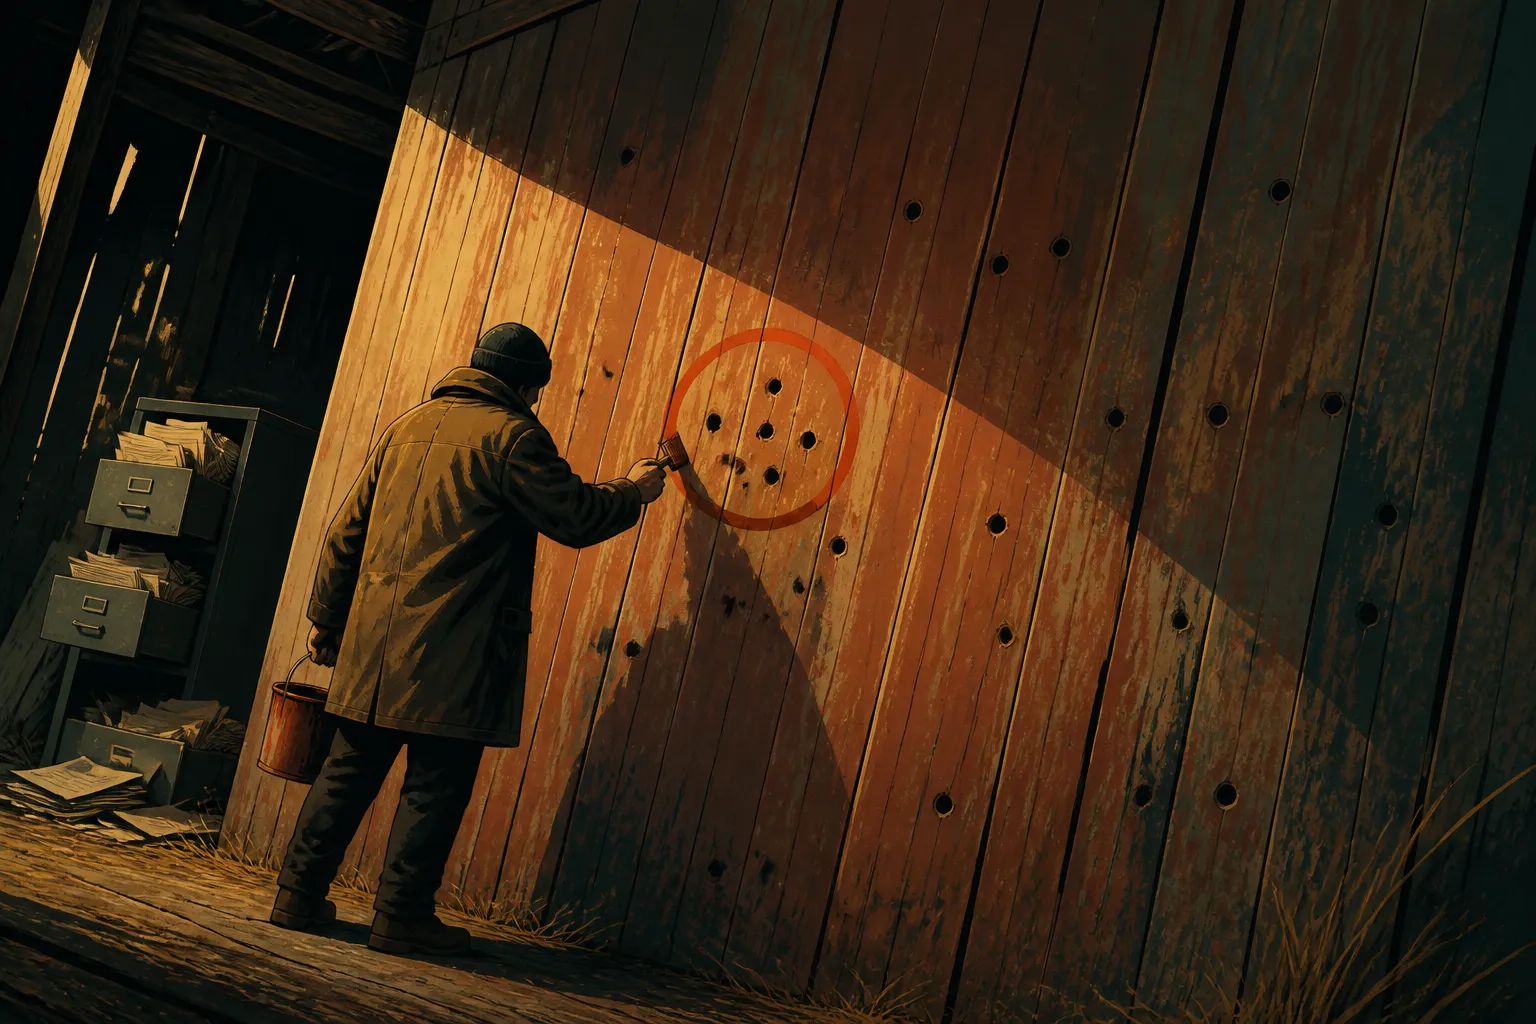
The old story goes like this. A man fires at the side of a barn, walks up to the tightest cluster of holes, and paints a bullseye around it. Then he announces himself a marksman. The Catalog of Bias never tells that story, and its entry on data dredging does not mention the sharpshooter at all. But anyone who has spent time with municipal files will recognize the move. The data is already in the cabinet. The paint is still wet.
What data dredging is
The Catalog of Bias defines data-dredging bias as a distortion that arises when the results of unplanned statistical tests are presented as though they came from a fully prespecified plan of analysis. Note where the fault sits. Looking at data is not the offense. Hiding how the looking was done is.
The term covers a family of habits, including fishing and p-hacking. In each, a researcher probes the data in unplanned ways, finds an attractive result, and reports it without saying how the analysis was carried out. The entry also stresses that this is often not villainy. Gelman and Loken (2014) observe that it can seem entirely appropriate to look at the data and construct reasonable rules for exclusion, coding and analysis that happen to produce significance. From the inside, it feels like diligence. That is what makes it hard to catch.
How the bias enters an analysis
Every analysis demands choices. How to treat outliers, whether to combine groups, which covariates to include. The literature calls these researcher degrees of freedom. Ideally, best practice guides them and a public protocol fixes them before anyone sees a result.
Without a protocol, trouble starts when a first pass lands near the significance threshold. A nudge here, an exclusion there, and the p-value slips under the line. The canonical version is plain: try several options, report the one with the lowest p-value, and say little about the rest that came up non-significant.
The catalog lists other forms. Fishing tests many variable combinations and reports the best-looking model. Some researchers decide whether to collect more data based on interim results. Others choose analyses after the fact. Then there is HARKing, hypothesizing after the results are known, which presents a hypothesis formed after the data as if it had been held beforehand. Each can yield false positives, and false positives are unreliable company.
Why the consequences matter
The catalog offers one striking example. Reviewers examined 93 randomized controlled trials and classified 22 as unlikely to have been p-hacked. Of those 22, only one produced a statistically significant result. The contrast hints at how much apparent support can rest on analytic choices rather than on any underlying effect.
The same entry goes on to a meta-analysis of progesterone, which found evidence that the treatment was not effective, with a risk ratio of 1.0. The source text breaks off there, so I will not guess at the rest of the figures or the conclusion.
The bias is not automatically disqualifying, either. Some of these practices are acceptable when transparently reported. The damage comes when authors fail to say how the results were generated, because readers can no longer weigh the evidence. A barn with a visible painter is a fair barn.
Questions and red flags for readers
Start with the plan. Was the course of analysis prespecified, and does a public protocol exist? Were the analytic choices reported, including the alternatives tried and set aside? Was the hypothesis stated before the data were collected, or built afterward to explain them? When judging a body of evidence, were the trials preregistered?
Then watch for the tells. A reported result that is the lowest of several analyses, especially when the others missed significance. Findings that sat just short of significance before the choices were made. Undisclosed decisions to gather more data or switch analyses after an interim look. A hypothesis dressed as prior that was formed late. And meta-analyses that are not restricted to preregistered trials, which deserve the same squint.
Open questions and limits of the evidence
Some honesty about the source is due. It does not mention the Texas Sharpshooter fallacy, so the link I have drawn is an analogy of mine, not something the catalog establishes. Treat it as a separate question.
The entry also omits its section on preventive steps, so practical safeguards are not described here. It does not say how to judge from a published paper alone whether an analysis was p-hacked, or how to separate exploratory from confirmatory work in everyday reasoning. And it says little in defense of exploration beyond noting that open reporting makes it acceptable. How much weight an exploratory finding deserves next to a prespecified one stays open.
Two plates to keep
Sources
- Data-dredging bias | Catalog of Bias
- Multiple Endpoints in Clinical Trials | FDA
- Using multiple primary endpoints in clinical trials with a focus on heart failure | Global Cardiology
- The Texas Sharpshooter Fallacy: Drawing Bullseyes After the Data Is In
- https://vertexaisearch.cloud.google.com/grounding-api-redirect/AUZIYQGfWJI61a9oFRi0tnP9I2WqbDT4mTe3YeL9n73Akoe_V_dtKlgsLp8CCNpQJlyFE_BTIfZ6G7WWGc0BZNMb1_B_vz02HZ1Q7PGkTq2xWdZtkEa-azN4RlQfeEnph4v6
- The Endpoint Hierarchy: Primary vs Secondary vs Exploratory| BSC®
- Multiplicity issues in clinical trials - Scientific guideline | European Medicines Agency (EMA)
- https://vertexaisearch.cloud.google.com/grounding-api-redirect/AUZIYQERzI20u3O0CMQjcwEwOm-68Hjc193xqhxaxko8CyNrngUEDW3Mrj1V9-ql53VF5pnOoihgez6DRKavg0lERG76cQXgfULK_xBynFBBQ1RooFneQy8qaLM8h3X1V__iwjOsTtBT-mjVKXCqBxDfebgShlr6Cfx5lIxIyY7vH7VNwasq1M5zwY6bRF-b6njg3qUC3BOcnaCwKwozVEEqElmX-0owyiEWisx7syPS
Marcus Adeyemi-Holt is a house writer for Deeperpectives, where he examines how ordinary routines reveal larger patterns in work, memory, and place. He draws on years of reporting on municipal records and oral histories to trace the quiet forces that shape everyday life.